Providers
Ce contenu n’est pas encore disponible dans votre langue.
Providers
Section titled “Providers”LM Nexus is local-first, not local-only.
You can run a model on the same machine, connect to a self-hosted server, point LM Nexus at an OpenAI-compatible endpoint, or use a supported external provider.
The shared provider layer means Chat, agents, Notes AI features, Quick Capture, and other parts of LM Nexus do not each need their own separate provider implementation.
Current provider types
Section titled “Current provider types”The provider registry currently includes paths such as:
- local Model Manager;
- Ollama;
- OpenAI-compatible endpoints;
- custom providers;
- GitHub Models;
- GitHub Copilot;
- OpenAI Codex.
A provider only becomes usable when its own configuration and any required runtime or CLI dependency are available.
Local Model Manager provider
Section titled “Local Model Manager provider”When Model Manager is active, it provides the local models that LM Nexus manages itself.
The provider layer does not download models or start llama-server processes. Model Manager still owns those jobs.
OpenAI-compatible and self-hosted services
Section titled “OpenAI-compatible and self-hosted services”Use an OpenAI-compatible or custom provider when the model server already exists outside LM Nexus.
Typical examples are:
- self-hosted inference;
- another local model server;
- a compatible remote service;
- a custom endpoint.
LM Nexus uses the endpoint; it does not try to take over the server that owns it.
Agents and providers
Section titled “Agents and providers”Agent Runtime asks the provider layer for model responses instead of talking to each provider directly.
The provider layer decides which configured endpoint/model to use and normalizes the request and response. Agent Runtime stays focused on tools, approvals, questions, and delegation.
Configuration
Section titled “Configuration”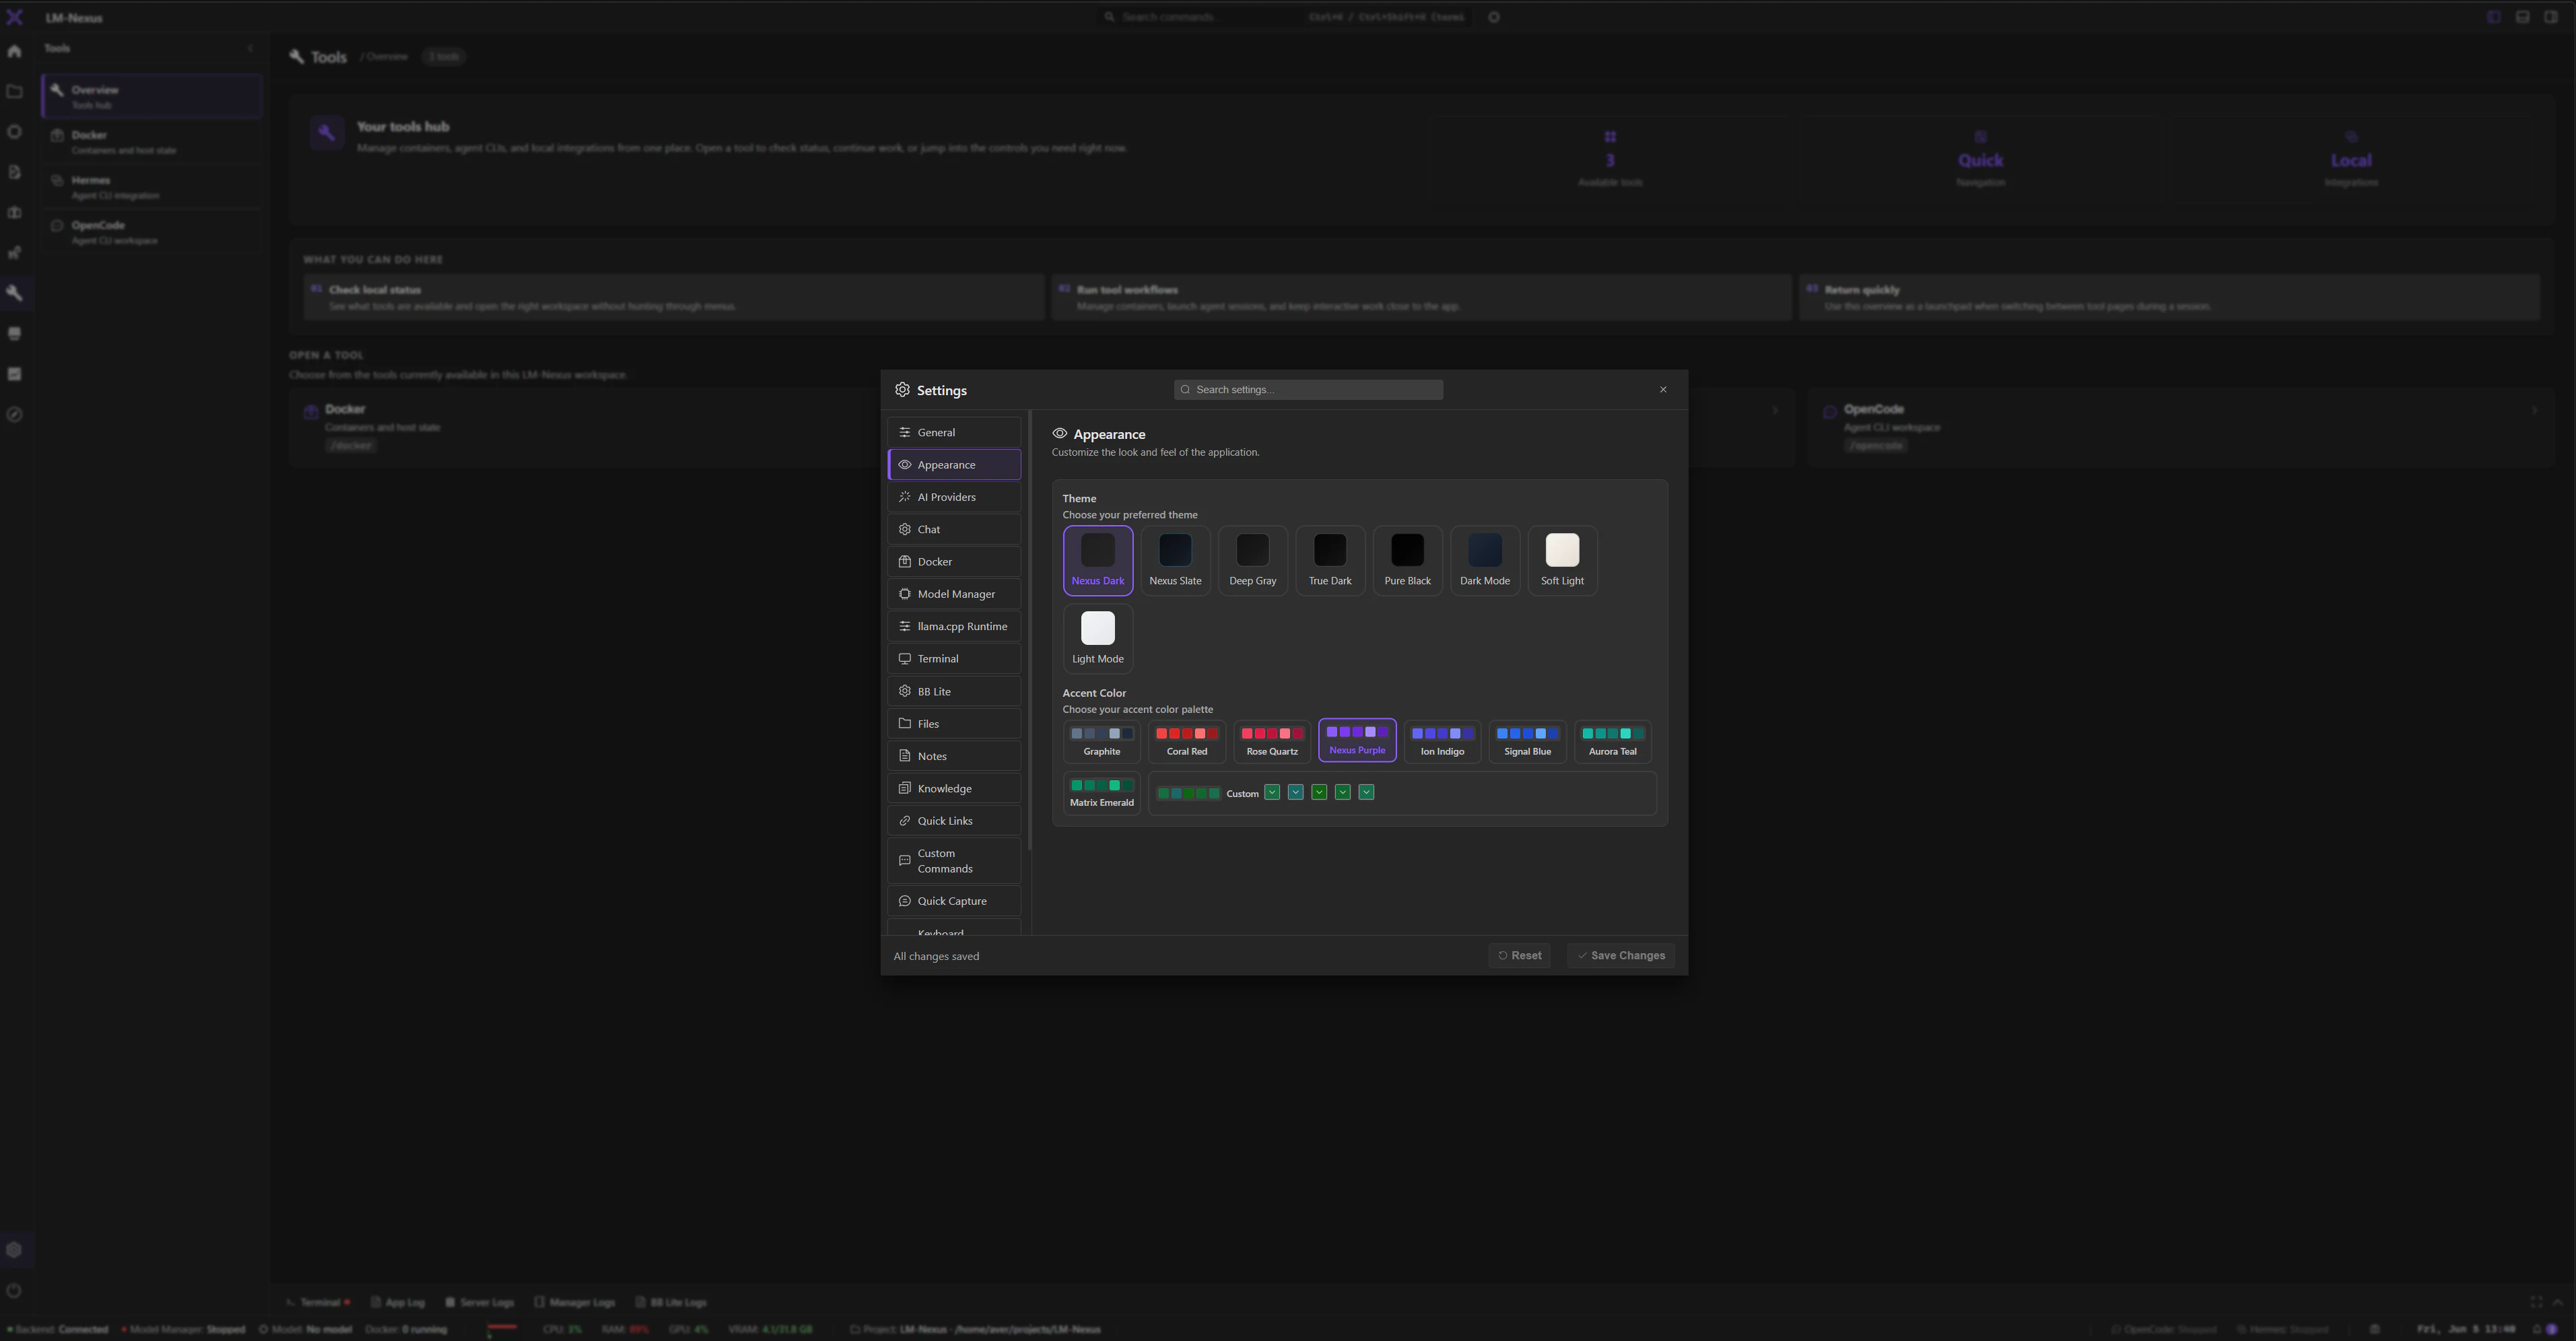
Provider settings and connection tests live in the settings for each provider.